Feature Engineering and Pipelines
Read at your own pace. Code execution, quizzes, progress tracking, and the AI tutor are available in the interactive view with JavaScript enabled.
Why Features Matter
Feature Engineering and Pipelines
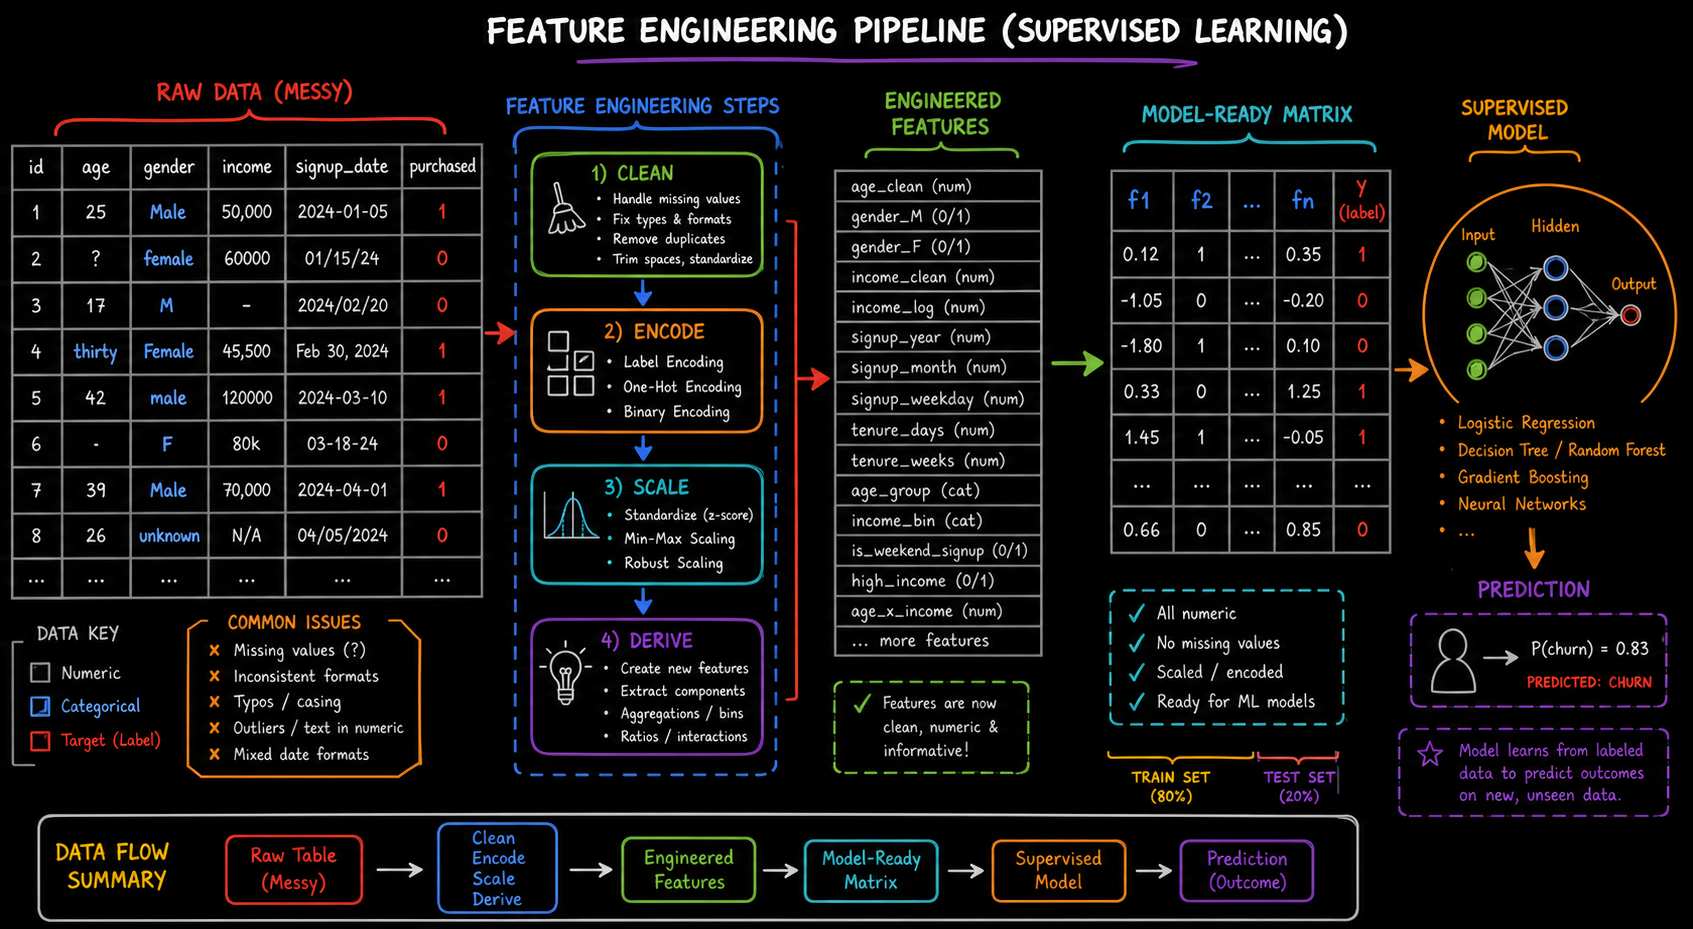
Now that we have trained supervised models, evaluated them with Train Test Split and Metrics, and studied interpretable splits in Getting to Know Decision Trees, we are ready for a practical question:
What exactly should we feed into the model?
Raw columns are rarely the best model inputs. Dates need to become durations, categories need numeric representations, missing values need a plan, and numeric values often need scaling.
For software engineers, feature engineering is similar to building a clean API boundary: messy external input comes in, validated and transformed data goes out.
CONTINUE WITH ALGODAILY PREMIUM
Keep going with the complete tutorial.
Unlock the remaining explanations and exercises, alongside the full learning library.
Explore Premium →