Deployment, Monitoring & Performance Tuning
Read at your own pace. Code execution, quizzes, progress tracking, and the AI tutor are available in the interactive view with JavaScript enabled.
Last Mile Matters
From lab to live
In Backtesting, Simulation & Replay, you proved ideas offline. Now the final step is making a trading system survive real market hours.
Deployment is not just copying a binary to a server. For HFT-style systems, it means:
- starting the right processes in the right order
- validating config before risk is exposed
- watching latency tails, feed freshness, order rejects, and inventory
- tuning only when measurements prove the change helped
- having a calm rollback or kill-switch path
This lesson ties together the entire course: market data, low-latency C++, networking, concurrency, OMS/FIX, book reconstruction, execution algorithms, market making, stat arb, and replay.

Production Shape
A simple live topology
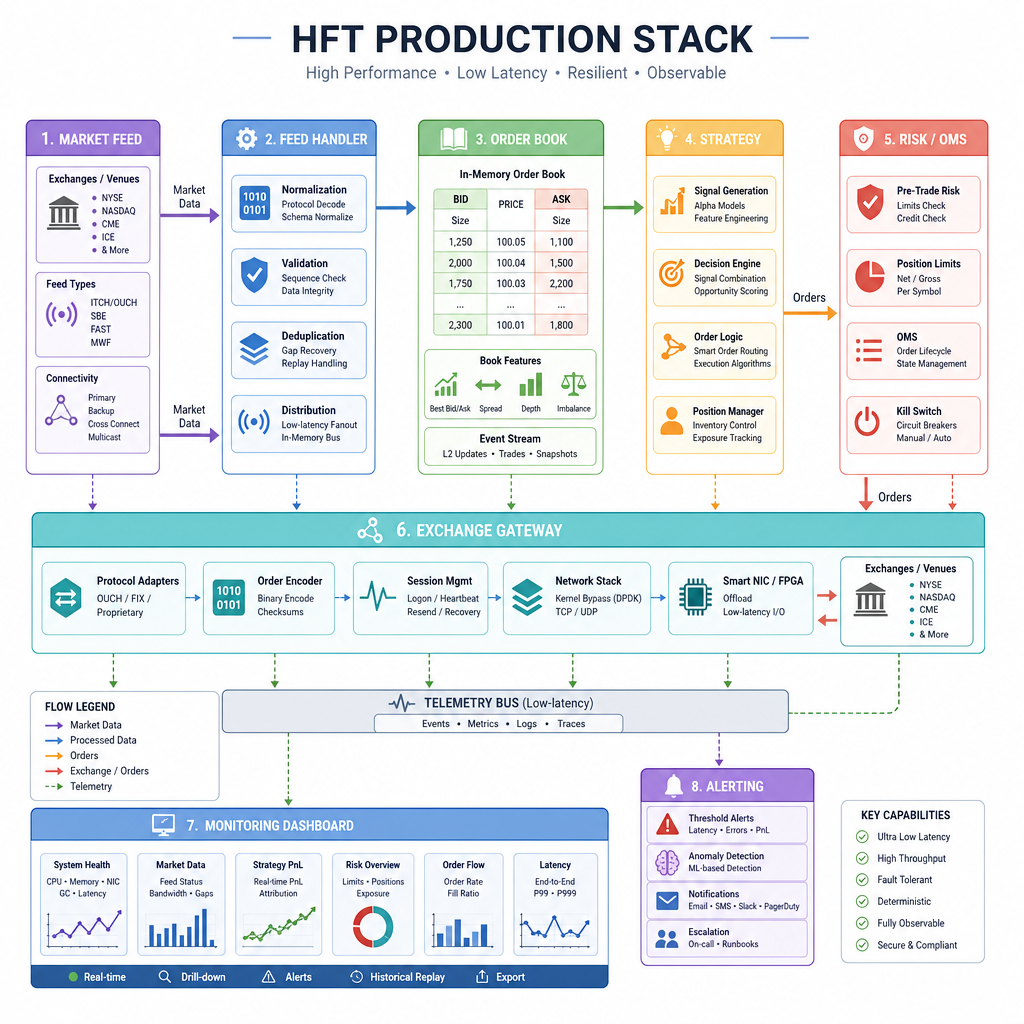
A production trading stack is usually split into cooperating services instead of one giant program.
Market Feed -> Feed Handler -> Book Builder -> Strategy -> Risk/OMS -> Exchange Gateway
                    |              |             |          |
                    v              v             v          v
                 Metrics        Snapshots      Signals    Orders/Fills
                    \______________ Monitoring + Alerts ______________/
From earlier lessons, you already know what each core component does. The deployment lesson adds the operating rules around them:
- supervision: restart or stop unhealthy processes intentionally
- configuration: deploy immutable, reviewed runtime parameters
- heartbeats: prove each component is alive
- rollback: return to a known-good build quickly
- audit logs: reconstruct what happened after the session
A good live system is boring: every component has a job, a health signal, and a failure plan.
Preflight Gate
Validate before launch
Before a live process can send orders, it should pass a preflight gate.
This is the deployment version of the guardrails you saw in Order Management & FIX Integration and Core Execution Algorithms. The system should reject dangerous config before the market opens, not after a bad order is sent.
Typical preflight checks:
- symbol is present and supported
- max order quantity is within approved limits
- max position is within risk limits
- kill switch is not already active unless you are doing a dry run
- feed freshness threshold is reasonable
The example below is intentionally small, but the pattern scales: validate, report, and refuse to trade if anything is unsafe.
```cpp
#include <iostream>
#include <string>
#include <vector>

struct Config {
    std::string symbol;
    int maxOrderQty;
    int maxPosition;
    bool killSwitch;
    int feedStaleMs;
};

std::vector<std::string> validate(const Config& c) {
    std::vector<std::string> errors;

    if (c.symbol.empty()) errors.push_back("symbol is empty");
    if (c.maxOrderQty <= 0 || c.maxOrderQty > 1000) errors.push_back("maxOrderQty outside approved range");
    if (c.maxPosition <= 0 || c.maxPosition > 500) errors.push_back("maxPosition outside risk limit");
    if (c.killSwitch) errors.push_back("kill switch is active");
    if (c.feedStaleMs <= 0 || c.feedStaleMs > 1000) errors.push_back("feedStaleMs is unreasonable");

    return errors;
}

int main() {
    Config cfg{"ESU5", 250, 100, false, 75};

    auto errors = validate(cfg);
    if (errors.empty()) {
        std::cout << "PREFLIGHT PASS: strategy may enter live-ready state\n";
    } else {
        std::cout << "PREFLIGHT FAIL:\n";
        for (const auto& e : errors) std::cout << " - " << e << "\n";
    }

    Config bad{"", 5000, 900, false, 5000};
    auto badErrors = validate(bad);
    std::cout << "\nBad config produced " << badErrors.size() << " errors\n";
    for (const auto& e : badErrors) std::cout << " - " << e << "\n";
}
```
Deployment Check
You are deploying a replay-tested market making strategy. Which issue should block live deployment immediately?
Observe The Loop
Monitoring is your live feedback system
Once deployed, your job shifts from writing code to proving the system is behaving.
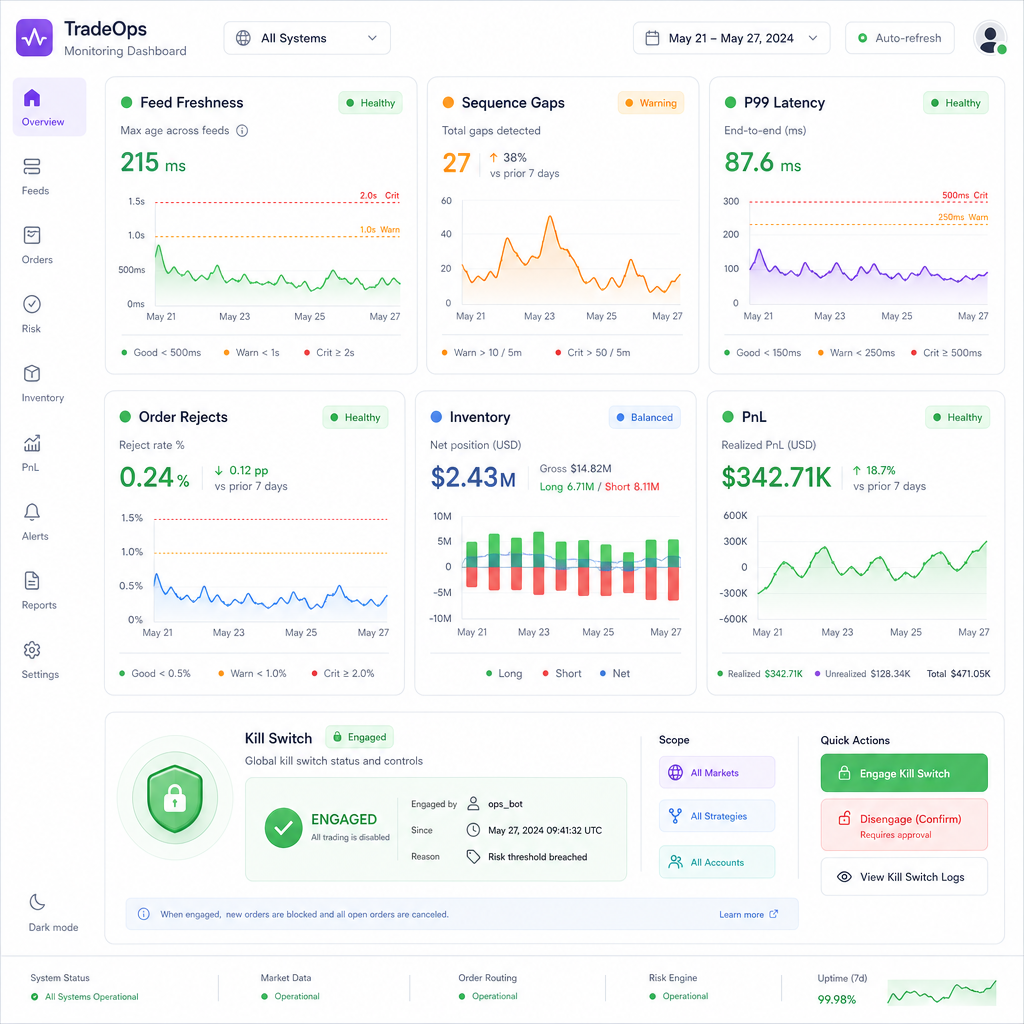
Useful HFT monitoring focuses on freshness, correctness, latency, and risk:
- Feed health: sequence gaps, snapshot recoveries, feed age
- Book health: crossed books, stale top-of-book, invalid levels
- Strategy health: signal age, quote count, cancel rate, inventory
- OMS health: rejects, pending orders, fill ratio, disconnects
- Latency health: p50, p90, p99, max by pipeline stage
- Risk health: position, notional exposure, drawdown, kill-switch state
Avoid dashboards that only show averages. In trading systems, the expensive failures often live in the tail: a delayed cancel, a stale quote, or a burst of rejects.
Tail Latency
Percentiles beat averages
Average latency can hide the exact events that hurt a live strategy.
If 99 messages are fast and 1 cancel is extremely slow, the average may still look fine. That one slow cancel can be the difference between being safely quoted and being picked off.
So production dashboards usually track:
- p50: normal case
- p90: busy but common case
- p99: tail behavior
- max: worst observed case
The small C++ example below calculates percentiles from observed latencies.
```cpp
#include <algorithm>
#include <iostream>
#include <vector>

long percentile(std::vector<long> values, double p) {
    std::sort(values.begin(), values.end());
    std::size_t idx = static_cast<std::size_t>((p / 100.0) * (values.size() - 1));
    return values[idx];
}

int main() {
    // Microseconds for a pretend order path: signal -> risk -> gateway ack
    std::vector<long> latencyUs = {42, 45, 44, 43, 46, 50, 48, 47, 52, 49, 55, 60, 58, 500};

    long p50 = percentile(latencyUs, 50);
    long p90 = percentile(latencyUs, 90);
    long p99 = percentile(latencyUs, 99);
    long maxLatency = *std::max_element(latencyUs.begin(), latencyUs.end());

    std::cout << "p50 latency: " << p50 << " us\n";
    std::cout << "p90 latency: " << p90 << " us\n";
    std::cout << "p99 latency: " << p99 << " us\n";
    std::cout << "max latency: " << maxLatency << " us\n";

    const long sloUs = 100;
    if (p99 > sloUs) {
        std::cout << "ALERT: p99 latency exceeds SLO of " << sloUs << " us\n";
    } else {
        std::cout << "OK: p99 latency within SLO\n";
    }
}
```
Tail Truth
True or false: if average latency is stable, p99 latency can usually be ignored in a live trading system.
Measure A Change
Tune with evidence
Performance tuning should be a loop, not a guessing game:
Baseline -> Hypothesis -> One Change -> Measure -> Keep or Roll Back
This connects directly to Low-Latency C++ for HFT, Networking & Kernel Bypass, and Concurrency & Lock-Free Programming. You already learned tools like preallocation, batching, cache-aware layout, and careful synchronization. In production, the rule is stricter: change one thing, measure the same workload, and compare tails.
The example below demonstrates a tiny benchmark comparing vector growth with and without reserve. Real trading benchmarks should use replayed production-like data, but the habit is the same.
```cpp
#include <chrono>
#include <iostream>
#include <vector>

long long runTest(bool useReserve, int n) {
    auto start = std::chrono::high_resolution_clock::now();

    std::vector<int> values;
    if (useReserve) values.reserve(n);

    for (int i = 0; i < n; ++i) {
        values.push_back(i);
    }

    auto end = std::chrono::high_resolution_clock::now();
    return std::chrono::duration_cast<std::chrono::microseconds>(end - start).count();
}

int main() {
    const int n = 2'000'000;

    long long noReserve = runTest(false, n);
    long long withReserve = runTest(true, n);

    std::cout << "push_back without reserve: " << noReserve << " us\n";
    std::cout << "push_back with reserve:    " << withReserve << " us\n";

    if (withReserve < noReserve) {
        std::cout << "Result: reserve helped in this run\n";
    } else {
        std::cout << "Result: reserve did not help in this run; measure again before deciding\n";
    }
}
```
Runbook Blank
In a deployment runbook, the emergency control that stops new order flow during abnormal behavior is commonly called the _____ switch.
Course Finish Line
Your final live-readiness checklist
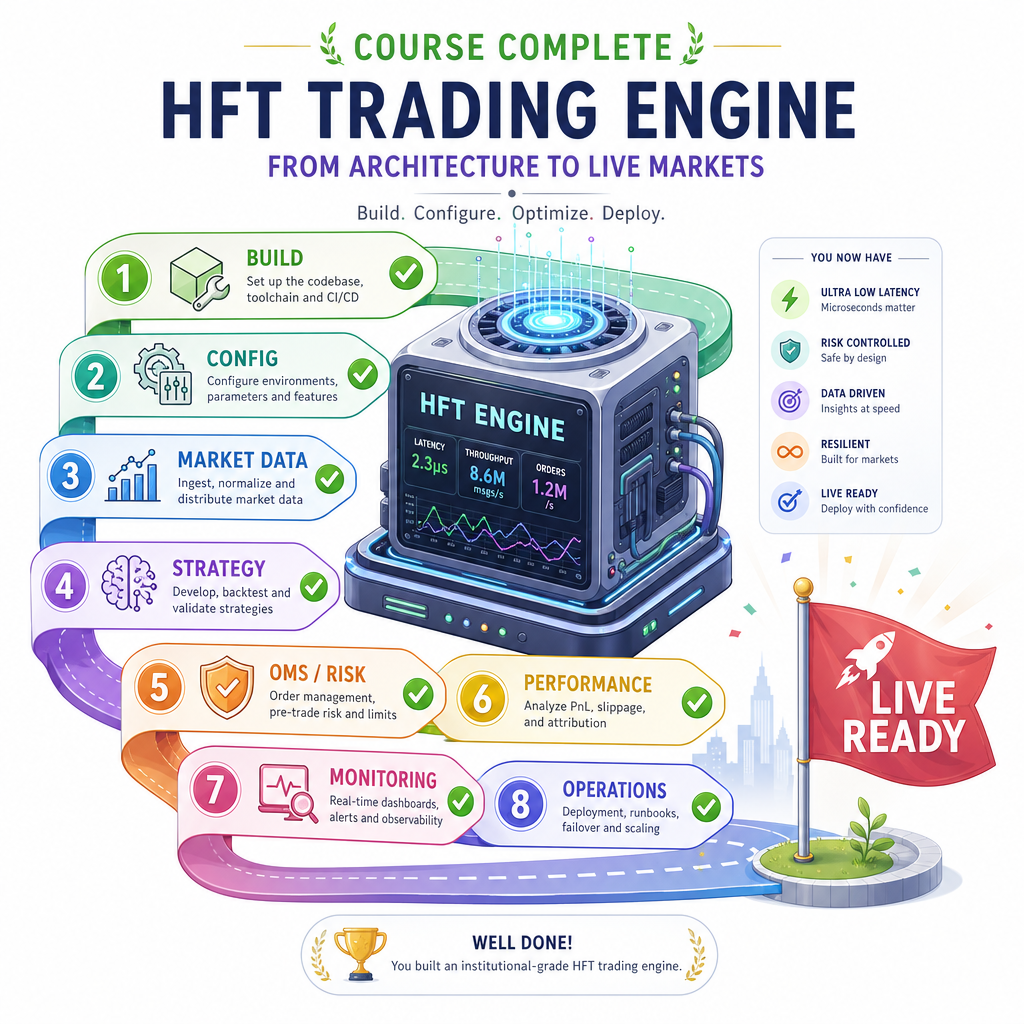
You have now walked the full path from environment setup to live operations.
Before any strategy goes live, confirm:
- Build: reproducible binary, known compiler flags, version tagged
- Config: reviewed limits, symbols, sessions, and feature flags
- Market data: sequence tracking, snapshot recovery, freshness alerts
- Strategy: replay-tested behavior and documented assumptions
- OMS/Risk: state machine, reject handling, position limits, kill switch
- Performance: baseline latency, p99 SLOs, CPU and memory headroom
- Monitoring: dashboards, alerts, logs, and post-trade audit trail
- Operations: startup order, rollback plan, on-call ownership
The big lesson: an algorithm is only one part of algorithmic trading. The production system around it determines whether it can trade safely, measurably, and repeatably.
From here, keep building small components, replay them with real-like data, instrument everything, and only trust improvements that survive measurement.